Salesforce backup preserves business records, files, relationships, and metadata from unintentional deletions, overwrites, and config errors. To ensure reliable Salesforce recovery, maintain recoverable backup versions, restore records in the order of dependency, map record IDs when necessary, and verify the results. Establish a backup frequency based on acceptable data loss and test recovery capabilities frequently.
Key Takeaways
- Salesforce backup should cover supported records, files, metadata, and relationship information.
- Native recovery options differ on their treatment of deletions, overwritten values, and configuration changes.
- Restoring related records can require dependency order management and source-to-target record ID translation.
- Backup frequency should reflect your recovery requirements and your data loss thresholds.
- Backup reliability is verified via representative restore tests.
- When choosing a Salesforce backup solution, review documented coverage, storage controls, and proven recovery performance.
What is Salesforce Backup?
Salesforce backup, as the name suggests, is your reliable protector that keeps a backup of your org data and metadata outside production, ready to restore supported information types to the known and safe state when/if you need it. A complete backup should include the records, the relationships between them, the metadata, and even the automation that defines the behavior of your org.
Sure, Salesforce keeps its own platform running, but it can’t tell when a bulk update went wrong in some way. Native data protection capabilities like the Recycle Bin or the Data Export are insufficient for backup purposes on their own.
The true test of any backup should be its recovery, no matter if the solution itself is native or third-party: it should restore all the records back, with all their relationships linked properly and working within a tolerable timeframe.
The nature of how orgs usually fail defines the importance of Salesforce data protection solutions. Common Salesforce data-loss scenarios include mass delete or some integration replacing newer values with older ones. In any case, the platform treats these actions as legitimate and processes them as usual, with very few options for reversing what went wrong – outside of an independent backup copy.
| Backup | Restore |
| Creates a recoverable copy of data | Uses a retained copy to recover data |
| Runs before an incident | Runs after an incident or during testing |
| Captures records, files, and supported metadata | Recreates or updates affected components |
| Measured by coverage, frequency, and retention | Measured by accuracy, completeness, recovery time |
What Should a Salesforce Backup Include?
Salesforce backups should protect both regular data and metadata. Data is the content of all the records and files. Metadata, on the other hand, refers to the way the records and documents behave and are structured.
By only protecting one of these, your organization risks ending up in a situation where the data is there without any layout, or vice versa. Salesforce’s official data backup and recovery recommendations as of October 2026 distinguish data from metadata while recommending routine backups and backups before major data operations.
What is the Difference Between Salesforce Data and Metadata?
Imagine an admin deleting a custom field in March and learning two months later that that custom field contained two years’ worth of renewal dates. The dates are regular data, and the field definition is metadata. Once the field is purged, both are gone, and to get them back you’ll have to recreate the field using the same application programming interface (API) name before loading the values into it. Having just a copy of the data isn’t enough if you don’t have a place to store it, and having a metadata copy would provide nothing but empty fields as a result.
Storing older versions of both allows you to restore your records to normal after an unfortunate change or situation.
How Do Files and Attachments Differ in Salesforce?
Attachments and records require separate coverage checks, as they’re stored separately from field values. So, a backup of your Salesforce Files and Attachments has to include the file content and also the link to the parent record at the same time.
What are Standard and Custom Objects in Salesforce?
What kinds of custom objects did the org gain in the last year, and is the backup aware of them? Standard objects like Account or Opportunity are often covered automatically. The ones that slip through the cracks are objects that were added later or those high-volume objects that were excluded to save storage at some point and never reconsidered.
A short scope review would help catch both of these by asking just a few questions:
- Does the backup list every object in the org today?
- Who approved each exclusion? When?
- Are field history and similar related records included where they matter?
- Does a new object enter scope automatically, or only when someone asks?
How Do Parent-Child, Lookup, and Master-Detail Relationships Work in Salesforce?
Restoring a Contact without its Account is identical to restoring only half a record. A lookup is an optional reference that’s configured in a certain way by default, making it so that the parent deletion would leave the child in place with an empty field.
A master-detail relationship works slightly differently, tying the child’s lifecycle to its parent, resulting in all delete actions cascading down to every child record.
Either way, all variations of references have to be stored in backups in their entirety – both the reference value and the ID it points to, as those tend to be the only way to reattach children to the right parents.
How Do Salesforce Flows and Triggers Affect Recovery?
Think for a second about what happens when a restore begins loading in records. Both Flows and Apex triggers start firing as if users were saving these records for the first time, often resulting in email bombardments or instances of freshly restored values being overwritten.
These consequences show why backing up automation configurations remains paramount, showing which of it is active so that people can pause it before the load and turn everything back on afterwards.
Salesforce Backup Components at a Glance
The table below takes each component of a Salesforce backup and showcases what it looks like in a real org, as well as what the restore would have to account for to proceed smoothly:
| Salesforce component | Example | Why it matters during recovery | Recovery consideration |
| Record data | Account name, Opportunity amount | Holds the business information users rely on | Earlier versions are needed to undo a bad edit |
| Custom object records | Subscription records in a custom object | Often carry process-critical data with no native substitute | The object and its fields must exist before load |
| Relationship fields | Contact to Account, Opportunity to Account | Tie child records to their parents | Parents are restored before children |
| Files | A contract PDF attached to an Opportunity | Working documents and evidence | Restore with the link to the parent record |
| Field and object metadata | Custom field, record type, validation rule | Defines what a record can hold | Recreate before loading data |
| Automation | Flow, Apex trigger | Changes data when records are saved | Can re-fire during restore and needs control |
| Access settings | Profile, permission set | Decide who can see restored data | Verify after the restore |
| Installed package settings | Managed package configuration | Can be hard to rebuild from memory | Capture alongside the rest of the org |
How Does Salesforce Data Get Lost or Corrupted?
Salesforce data gets lost or corrupted from the changes made inside the org. It tends to happen even if the user or other systems performed their intended actions exactly as they were configured. Platform outages are also rarely involved.
Most incidents fall into five types of scenarios, with each incident leaving a different kind of damage to repair or recover from. GRAX discusses how all these play out in practice in its article on Salesforce data incidents.
Accidental Record Deletion
Let’s say you were rushed on a Friday afternoon and accidentally mass-deleted the wrong list view of Opportunities. As a result, the records would move to the Recycle Bin in most cases (unless the hard delete option was enabled), waiting for a little bit in case someone wants to restore everything in just a few clicks. A retained backup becomes the preferred recovery option when native undelete is unavailable, bringing records back together with their child records and reconnecting each to the right parent.
Bulk Update and Import Errors
Nothing gets deleted here. Paradoxically enough, this makes the damage more difficult to notice. For example, if someone accidentally imports email addresses into a phone field for thousands of records, you won’t have an entry in the Recycle Bin for that. The original values would still be stored in the field history, but only for those fields that had tracking turned on.
Proper recovery would require the value each field held before the import, as well as a way to write back only the fields that were changed, nothing else.
Integration and Automation Overwrites
A sync that runs every night at 2 AM might pick a stale extract from the source system and write it over the live values. By 9 AM, sales reps have already edited some of those values, meaning a direct rollback would erase legitimate work. A Flow looping over a bad data set would simply create the same pattern. The solution here is to pause the entire job and start comparing values to ensure that only the affected fields are restored.
Deployment and Configuration Errors
Whenever a release updates your production Flow to an older version from the sandbox, you might only discover that several days later, when the stale logic stamps were applied to all new Cases.
Both the data and the configuration that produced it are wrong here. An earlier Flow version would be required to repair this issue, along with all the values the affected Cases held before.
Malicious Deletion or Change
Both an authorized user acting maliciously and an attacker with a compromised admin login can potentially delete or edit records en masse. Actions like these are completely valid from the platform’s perspective: both have legitimate access credentials, after all. You won’t even be able to restore everything from a backup if it was reachable with the same login credentials, so it’ll all depend on whether your company has a data copy outside the access range of the malicious actor.
What Can Salesforce Recover Natively?
Recently deleted records and export data on a schedule can both be recovered by Salesforce natively, in addition to a separate paid add-on for general backup and restore purposes. With native capabilities, you can reverse some deletions within a limited period of time, but you won’t have older versions of data that you’ve overwritten and won’t be able to roll back to previous configurations. As you start to plan your strategy for backing up and recovering Salesforce data, remember those limitations.
Which Free Salesforce Recovery Tools are Available?
Recycle Bin, Data Export, and Data Loader are the main options that Salesforce provides as of October 2026.
15 days. That’s how long the deleted records remain in the Recycle Bin. Administrators with the Modify All Data permission can also undelete such records directly from the org-wide Recycle Bin. That said, there’s also a hard delete option that’s available in certain cases, like in a Bulk API job where it can be enabled. These records never enter the bin to begin with.
Data Export creates comma-separated values (CSV) files of an org’s data once every week at its fastest. Its speed is regulated by the org’s license tier, with many options only having a one-report-per-month option available. Salesforce emails the owner a link to the exported files and deletes them 48 hours after that email is sent. Attachments and files are included only if selected, and configuration needs a separate backup because Data Export covers data without formula and roll-up summary fields.
Another tool called Data Loader can move information in bulk through the API. It has an Export All operation that even includes the soft-deleted records, allowing users to capture deleted values before the Recycle Bin is emptied. That said, loading these records back into the environment would result in brand-new IDs being assigned, so someone would have to remap all the lookup connections that used to point to the old IDs.
Salesforce’s Paid Backup & Recover Add-On
Backup & Recover is a paid add-on Salesforce sells for this exact purpose. It’s available for Enterprise, Unlimited, and Developer Editions, promising automated daily backups for both data and metadata. It provides backup comparison, restore preview, granular restore capabilities, retention policies, and Shield encryption support. The metadata restore aspect of the solution includes a pre-defined list of component types it supports, such as flows, layouts, profiles, permission sets, and reports. The tool itself even has a separate add-on for Continuous Data Protection that can capture changes between backups.
Salesforce also revealed the next generation of this solution called Salesforce Backup & Recover Next, promising FedRAMP High compliance and better performance, among other features. It was launched back in April 2026 for select regions, promising further expansion in the near future.
What are the Limitations of Salesforce Native Recovery?
The features covered below are great at handling a very specific issue: a recent deletion that was noticed within days and could be recovered with its relationships intact.
As it stands, most of the actually problematic backup-related incidents in Salesforce are different. For example, it could be an overwrite from an import or sync, leaving nothing in the bin and barely any option to recover past values outside of the field history for tracked fields. Data Export cannot cover metadata alongside regular data, necessitating all the configuration coverage to be established separately; even CSV restores are severely limited by the need to manually figure out load order and reference mapping without going over the API limits.
The table below offers a visualization of how native Salesforce capabilities stack up against Salesforce’s own add-on and dedicated backup solutions in the most common recovery scenarios:
| Recovery need | Standard Salesforce tools | Salesforce Backup & Recover | Dedicated third-party backup |
| Undo a deletion within days | Recycle Bin undelete; 15 days to do so | Restore from a retained backup, within the configured retention period | Varies by product; check retention and whether restore works after the bin is emptied |
| Undo a hard delete | No self-service option | Restore from a backup taken before the delete | Possible when the product captured the record before deletion; confirm how deletions are tracked |
| Undo an overwrite | Field history for tracked fields only | Compare to a backup and restore at field level | Varies; ask about retained versions and field-level restore |
| Restore configuration | Not covered by Data Export | Metadata backup, with restore for the supported component types | Varies; ask which metadata types are captured and which can be restored |
| Restore related records | Manual load in dependency order | Salesforce describes relationship-aware restore | Varies; ask for a live demo with your own parent-child data |
What Happens to Salesforce Relationships During Backup and Restore?
Record IDs are what maintain relationships between data elements during backup and restore in Salesforce. If your restore imports records in a bad order or gives them new IDs without proper remapping, it’ll spawn a lot of broken lookups and orphaned children records – but Salesforce would still accept it as if nothing happened.
Proper relationship restoration implies rebuilding the entire dependency order and remapping all the IDs. Once all that’s done, one should make sure that every reference resolves correctly.
How Do Salesforce Record IDs Affect Restored Relationships?
Every Salesforce relationship is a separate field storing the ID of another record.
- A lookup field can be empty in order for a child record to load without its parent and without system errors.
- A master-detail field has to be mandatory to prevent situations where a child record is inserted without its parent existing in the same environment.
- Custom relationships follow these rules as well, including any junction object linking two parents using master-detail fields and polymorphic fields like the related-to field on a Task.
Depending on how exactly a record comes back, IDs can behave differently. Undeleting something from the Recycle Bin would keep the original ID, but inserting a record from a backup environment would automatically create a new ID, forcing all references to the past ID to be repointed.
Restore Order, Orphans, and Referential Integrity
Parent records should always come back first. Children follow parents, and any record referencing those children follows after.
An orphaned record is a self-explanatory case of a child record with its parent reference being either blank or incorrect.
Referential integrity makes sure each reference points to an existing record. Salesforce’s enforcement of this integrity is strict for master-detail relationships, but they become a lot less strict when it comes to lookups, enabling situations where a restore was finished with every row loaded and still spawned a massive number of integrity issues.
Example: Recovering an Account and Everything Beneath It
The tree below shows a customer Account, along with all the records hanging from it:
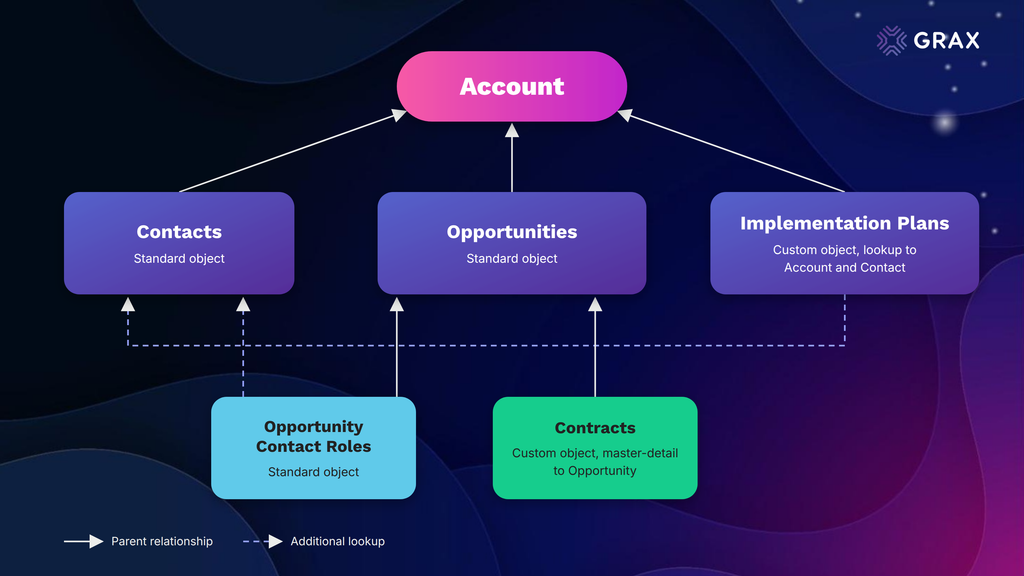
This example assumes the Account has no closed-won Opportunities or other records that could block its deletion. It also assumes Contracts use a master-detail field to Opportunity, while Implementation Plans use lookups to Account and Contact that clear the value on delete. If the Account is deleted and the Recycle Bin is emptied before restoration, Salesforce removes its Contacts and Opportunities too, along with the Opportunity Contact Roles and Contracts attached to them. The Implementation Plans remain in the org with blank Account and Contact fields.
Use the wrong order in the loading process, and you’ll get a lot of Contacts pointing to an Account ID that no longer exists. The load would either fail because of this or produce Contacts with no Account. Opportunities behave the same way, too, and Contracts will straight-up fail because their master-detail field would look for a parent that isn’t even there.
The correct loading order starts with the Account that receives a new ID while the backup records the pairing between old and new. Contacts and Opportunities are next, with their Account references being swapped to the new ID. Opportunity Contact Roles are next, as they reference both a new Opportunity and a new Contact. Contracts follow Opportunities. The Implementation Plans are last in line, updating Account and Contact fields to the new IDs. The last step is to check all the counts and references against the backup before anyone can start relying on the newly restored records.
How Does Salesforce Data Recovery Work?
Salesforce data recovery takes you through eight steps, beginning with what has been impacted and concluding with what has been recovered. It’s crucial that you follow these steps in order: even a successful restore will have broken data if you skip the dependency work.
Whether you’re using a managed backup or native exporting, data backup and recovery in Salesforce follows the same rough order; it’s just a matter of how much you do of each step manually. This process order is recommended, but isn’t something that Salesforce mandates.
Part 1: Define the Incident
Recovery starts with scope identification, as everything that follows will depend on knowing what changed and when.
- Begin by identifying the incident and the data affected. Establish what exactly happened, which objects and fields were impacted, and the specific timeframe of it all. You may be able to narrow that window to just a few hours when field history and the integration logs are involved.
- Establish the correct recovery point. Find the most recent backup before an incident occurred. If there were any legitimate changes to the data after that point, make a quick note about those so that they won’t disappear as a result of a full rollback.
[GRAX TEAM: screenshot] Timeline of backup points for an object/record with the incident time explicitly marked. Confirm which view in the current product shows this most cleanly.
Part 2: Prepare and Run the Restore
The four steps that follow account for most of the work, and most of the errors also happen here. What you’ll be trying to do here is to restore as few records as possible to repair the damage in an order that the model would accept.
- Determine the dependent and related records, listing the parents and the children for each affected record. The list this step creates would serve as the dependency map for the load.
- Next is the comparison of current and historical versions: matching the live records with the ones you backed up to identify any differences. The comparison shows which records the incident damaged and which users made valid changes since then.
[GRAX TEAM: screenshot] A side-by-side comparison with current and backed-up field values for one record.
- Select the data and metadata to be retrieved. Choose only what actually needs to return: all the fields on a deleted record or just one field overwritten by an import process. Be sure to include any metadata that might be necessary, like a deleted custom field.
- Restore the correct dependency order by loading parents first, followed by recording the old-to-new ID pairs and repointing every reference before the children are loaded. Any automation that fires on the load should be paused beforehand.
[GRAX TEAM: screenshot] The restore selection screen with related records included, if the product shows the dependency order.
Part 3: Verify and Record the Result
A restore can only be considered “finished” when the data has been checked properly, so these two last steps carry just as much weight as the load itself. You may think the record counts match, but that may not include any information about broken relationships. All the checks have to run in layers because of that, and the written record of all you’ve done would be invaluable later on, in case an auditor or the next incident response needs it.
- Validate relationships and record counts, comparing restored counts against the backup before making sure that all lookup and master-detail references resolve to a real record. The best bet is to spot-check field values on a random sample of records.
- Recovery efforts documentation is paramount for any subsequent recovery actions. It should be a recording of the incident itself with all the recovery points used, records restored, approvers, and other important details.
[GRAX TEAM: screenshot] A validation or restore summary view, if possible.
How Often Should Salesforce Be Backed Up?
When considering the best backup frequency for Salesforce, think about these two things: how much of your data can you afford to lose, and how quickly do you need the data to be returned? If your records change constantly and carry revenue, they require either frequent or continuous capture. The most fitting interval depends on how much data loss the business can accept.
Choose backup frequency based on the organization’s approved recovery point objective.
What are RPO and RTO in Salesforce Backups?
Recovery point objective (RPO) refers to how much data your systems can afford to lose, i.e., in what amount of time. A daily backup creates a potential recovery-point gap of up to 24 hours. The RPO that was actually achieved also depends on whether each backup completes, how changes are captured, and how quickly an incident is noticed.
Recovery time objective (RTO) is the maximum amount of time the business can go before restored data becomes operational. Your backup frequency sets your RPO, while the restore period determines your RTO, taking into account everything from locating the records to validating the result.
Learn more about setting both in GRAX’s guide to RTO and RPO for Salesforce.
How Do You Pick a Frequency for Salesforce Backups?
No interval works for every org, so the table below highlights different factors that move the decision for six common environments. The last column lists the criteria for setting each environment’s backup window.
| Salesforce environment | Change frequency | Data-loss impact | How to set the backup window |
| Production, high-volume transactions | Constant | Lost orders and customer commitments within minutes | Set the maximum acceptable loss window from transaction volume and the financial impact of every hour lost |
| Production, regulated data | Moderate to high | Compliance exposure on top of lost records | Set the window from regulatory and audit requirements; keep evidence of each backup run |
| Production, sales and service teams | Moderate | Rework of recent pipeline and account updates | Set the window from how much recent work the team could realistically re-enter |
| Objects fed by integrations | Bursty, in scheduled batches | Bad sync overwrites at scale | Align backups with the integration schedule, with one before and one after each major job |
| Full or partial sandbox | Low | Delayed testing and development | Back up when the sandbox holds work worth keeping, and before a refresh |
| Developer sandbox | Minimal | Minor lost setup work | Back up on demand, when the work in it would be costly to recreate |
How Do You Test a Salesforce Backup?
Backup testing involves restoring a sample into a sandbox and comparing it with the original, noting how long that process takes. Remember: a backup that wasn’t ever tested is nothing more than an assumption, a promise that must be made real with the correct testing procedures. Regular backup testing should be a part of any company’s schedule, along with immediate tests after every major change to the org.
Run a Test Restore
First, choose a sample large enough to operate like an actual org. You’ll need a couple hundred records of an important object (Accounts, for example), with its children and associated custom objects and their files.
Make sure to sketch out those dependencies before anything actually executes. Choose the recovery point you’d use in the aftermath of an incident (generally a backup from shortly before a known change), and note why you chose it.
Restore into a sandbox instead of production, and make sure to disable outbound email and integrations to avoid leaking test results to customers. Once that’s done, work through the checklist in order (presented below).
Counts come first to avoid making everything below them unreliable, followed by relationships that have to all land on an appropriate restored record. When comparing field values, bear in mind that dates and picklist values often lead to mapping mistakes. Check that the metadata your data depends on (like custom fields and record types) actually exists in the target environment.
Keep track of the full journey from first action to successful recovery, as that will be your actual recovery time to compare with the target. Finally, list what you learned and what you changed to fix or improve the process.
Salesforce Restore Testing Checklist
Refer to the list below as your pass/fail report for each run. Any line that wasn’t checked off will be a finding to correct before the next run.
The sample includes one parent object, all of its child records, and one or more custom objects.
Dependencies for the sample were recorded prior to the restore being initiated.
The recovery point is documented with justification for its selection.
The restore was performed in a sandbox with outbound email and integrations turned off.
Record counts for every object are consistent with the backup.
Each of the lookup or master-detail references resolves to a restored record.
Sample record field values conform to the backup, dates and picklists included.
Custom fields, record types, and other metadata are present and match.
Flows and triggers didn’t generate duplicate values or overwrite restored values.
A period from start to validated result was timed and compared with the target value.
Results and any gaps are captured, with the runbook updated as well.
Why Can a Salesforce Restore Test Pass Despite Data Errors?
It’s a fact that any test could pass (or fail) for the wrong reasons. When row counts match, that doesn’t necessarily mean the references will resolve correctly. When a restore completes without errors, it doesn’t necessarily mean that the right values came back. Sampling fifty records isn’t going to showcase the issues with volumes and API limits that would be evident during a restore of a million records.
Performing a test once, a long time ago, isn’t going to tell you anything about the way your org operates today. That said, if you define your success as the complete set of checks in the aforementioned list and repeat them regularly, you shouldn’t encounter most of these issues.
How Do You Evaluate Salesforce Backup Software?
While comparing Salesforce backup software, take a look at what can be restored and who controls the data in the storage. Both of these factors can be confirmed via a restore test. The following checklist contains fourteen different criteria separated into eight rows; it can go straight into a request for proposal (RFP) if necessary. The text sections under it explain the most important judgment calls – three of them.
Salesforce Backup Software Evaluation Checklist
The right-hand column provides an answer that’s worth accepting. Anything less specific than that is a good justification to ask for a demonstration.
| Criterion | Questions to ask | A strong answer |
| Backup coverage; data and metadata protection | What does the backup capture, and are data and metadata kept in step? | A published scope list with documented exclusions, and both captured together |
| Backup frequency; point-in-time recovery | How often can each object be backed up, and can a record return to a chosen moment | Per-object schedules from daily to continuous, with retained versions to restore by date and time |
| Granular recovery; relationship-aware restore | Can one field or record be restored alone, and how are dependencies and IDs handled? | Field-level restore with comparison to current values, and automatic ordering and ID remapping |
| Recovery testing; RPO and RTO | How are restores rehearsed, and what recovery times do customers see? | Built-in restore tests and measured times, with the method stated |
| Storage ownership; data residency | Where are backups stored, and who controls access and region? | Customer-controlled storage or clear contract terms, with region confirmed in writing |
| Security and encryption | How is data encrypted in transit and at rest, and who holds the keys? | Documented encryption with key control options |
| Deployment mode; API limits and scalability | What deployment models are offered, and how does it behave under API limits at the org’s data volume? | A model that fits security policy, with stated throughput and a plan for large objects |
| Access to historical backup data | Can backups be queried or exported outside Salesforce, and what happens at contract end? | Open formats and a defined exit path |
What Should a Salesforce Backup Software Demo Show?
Simply ask your candidates if they can show you their support for relationship-aware restores – you want to see it with your own eyes. Come up with an example of a customer Account that was deleted with its Contacts, Opportunities, and custom child records for long enough that the Recycle Bin is already empty. Follow the way the software orders the load and remaps IDs for the Contacts to land on a new Account, then ask it to restore a single overwritten field on one Opportunity without touching the rest.
A vendor that only answers with a slide instead of a live restore tells you important information, even without using their words. Try asking to repeat the demo with your own data if possible.
Who Should Control Salesforce Backup Storage?
External backup copies are supposed to carry your personal data outside of Salesforce, so all of the obligations from inside the org now apply to the copy. Ask where that copy lives and who has the keys to it. Also try asking what the vendor will remove when the contract ends. GRAX covers the wider issue of sensitive information and compliance in its article on Salesforce PII and sensitive data.
What are the Warning Signs When Listening to Vendor Answers?
Some of the vendor responses might slow down the evaluation process. Stating that the coverage includes everything without the specifics usually means the exclusions do exist, but they’re unwritten. Request specific values for recovery time, such as the amount of data or the recovery method. Alternatively, if a metadata claim merely ensures that the files are exported with no restore path, it might mean that half of your org would remain unprotected.
Stay on top of the API usage, as well. If there’s no specific information about API consumption, a backup might just burn through all of its daily limits at once, disrupting integrations the org actually depends on. Even references deserve some scrutiny, as a customer with a few thousand records and a restore job at tens of millions of records are nowhere near the same in terms of speed, completeness, and more.
Finally, make sure to read what the contract says about leaving, ensuring that there’s an option to export all historical backups in an open format for your data to stay with you.
How Does GRAX Approach Salesforce Backup and Recovery?
GRAX lets you export your Salesforce data and metadata to storage you own, in your own cloud account or on-premises, keeping version history for each record. You can restore at the field level, the record level, and include related child records if needed. Backups can be scheduled to run as often as every hour, and users will keep access to their data outside Salesforce.
How Does GRAX Back Up Salesforce Records?
GRAX installs as a managed package directly into your Salesforce, so you can easily access your data through the API. Scheduled jobs will pull anything that’s new or changed since the last run, adding a version to the record’s history. Deleted records are also tracked after they’ve been backed up; backup syncs for deletions happen on an hourly schedule by default. Metadata checks happen on a daily schedule by default. Finally, GRAX automatically throttles itself when your org’s API limit reaches 80%, avoiding conflict with other org integrations.
Where Does GRAX Store Salesforce Backup Data?
The diagram below follows a record from the Salesforce org into storage and back out again:
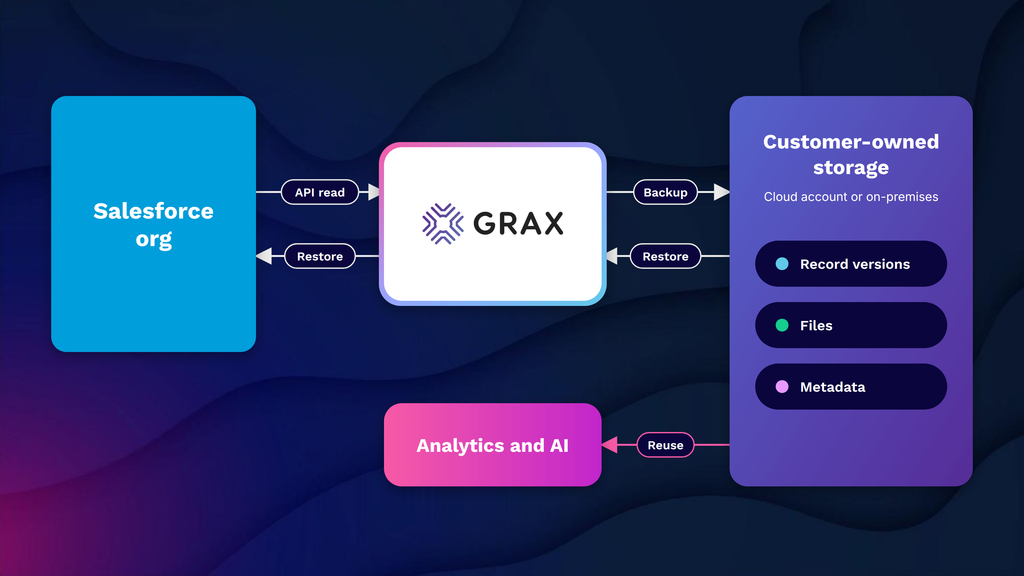
alt text: Diagram showing a Salesforce org read by GRAX and backed up to customer-owned storage that holds record versions, files, and metadata. Restores flow from that storage through GRAX back to the org, and a separate arrow leads from the storage to analytics and AI.
The backup is conveniently filed away in your own cloud account or in on-premises storage, depending on your preference. Every single version of a record is also neatly stored in a readable, queryable Parquet format for your analytics & AI teams, so there’s no need to return to Salesforce to query history. GRAX’s Data Lake & Lakehouse are built on the same files, as well.
How Does GRAX Restore Records and Relationships?
Restore works at the field or record level, choosing records by search or supplied as a file/ID list. A point-in-time restore returns live records to a specific date and time, while the Create Records restore rebuilds deleted ones, leaving it up to the end users to choose how many levels of child records come back and which objects to skip. Even though Salesforce assigns new IDs to every restored record, GRAX keeps the link to the original ID in its environment to keep the history consistent.
How Does GRAX Protect Salesforce Backup Data?
GRAX is SOC 2 Type 2 audited; its data is encrypted in transit (TLS 1.2) and at rest with the storage provider’s standard encryption protocol. The platform also respects Salesforce’s permissions in fields and sharing. Healthcare organizations can access the applicable HIPAA requirements and contractual safeguards.
GRAX’s limits are openly documented. Some objects aren’t queryable through the API and thus are listed as unsupported. Restores also run only one job at a time under the integrated user’s permissions. Check the object list against the org to be sure. Learn more about GRAX’s full capabilities in their backup and restore overview.
FAQ
How often should Salesforce be backed up?
It all depends on how much data you can risk losing. If your business is one in which revenue figures change by the minute, you probably need short capture intervals or even continuous capture. But if things are a little slower, a daily backup may be sufficient. Either way, add out-of-schedule backups before deployments, mass updates, or sandbox refreshes.
Does Salesforce automatically back up all my data?
Not out-of-the-box. You still have access to the deleted records for 15 days via the Recycle Bin, and the Data Export tool can create CSV snapshots once a week or once a month depending on the Salesforce edition. Neither option stores earlier versions of the data, though, which is why Salesforce also sells a paid add-on called Backup & Recover for automated backups and a slightly more extensive feature set.
Can Salesforce metadata be restored together with records?
It depends on the tool. Data Export doesn’t capture metadata, so configuration would have to come from a separate metadata backup or a deployment history. Salesforce’s Backup & Recover restores a defined list of metadata types.
The best approach is to capture metadata alongside data to avoid encountering missing fields and other issues during restore, but not all third-party Salesforce backup tools can offer that.
How often should Salesforce recovery be tested?
One test every quarter tends to be a good starting point, in addition to an out-of-schedule test after every major backup configuration change. Each test has to restore a sample into a sandbox, compare it with the source, and note down the time it takes to do everything.
Can deleted Salesforce records be restored with their relationships?
You can recover deleted items from the Recycle Bin within 15 days, and they will still have the original ID, so you won’t lose any of your references. If the bin is emptied or data is hard-deleted, you can still restore from a backup: parents must be loaded first, and then every reference has to be remapped to the new IDs. Some products do this more or less automatically, so ask candidates to demonstrate restoring a parent with its children.
What is point-in-time recovery in Salesforce?
With point-in-time recovery, you can retrieve a field, a record, or a set of records to the way they were at a given date and time. The process also requires a backup that keeps multiple versions of the same data, making it easier to select the exact moment before an incident.