Salesforce, SOQL, and Limits

Salesforce, a cloud-based Customer Relationship Management (CRM) system, is one of the richest sources of data for business analysis and intelligence.
Structured Query Language (SQL), a language for querying, filtering, joining, and aggregating data, is one of the most widely used tools for data analysis. One of the primary tools for analysis and reporting on the Salesforce platform is Salesforce Object Query Language (SOQL), a dialect of SQL that lets you query Salesforce data directly on the platform.
But as any Salesforce data admin knows, SOQL has some major limitations and challenges. Some of the main issues are:
- Hard limits on the length of a query string (MALFORMED_QUERY)
- Hard limits on row count and field count in result sets (QUERY_TOO_COMPLICATED)
- Hard limits on how long a query can take to run (QUERY_TIMEOUT)
- Limited WHERE semantics in queries (SOQL limitations)
- No JOIN semantics in queries (relationship query limitations)
- No ability to JOIN against other data sets outside of Salesforce
These problems get worse and worse as Salesforce and company-wide data sets grow in complexity and scale.
Traditionally this means you need to set up a database or data warehouse, and load Salesforce data into it before you can start doing real SQL queries and analytics.
But there is a database – DuckDB – that has matured into a widely-adopted standard for exactly this kind of work, unlocking true SQL abilities and eliminating the challenges of SOQL, traditional database servers, and Export-Transform-Load (ETL) processes. Combined with GRAX’s data warehouse and data API capabilities, it’s easy to unlock advanced SQL analytics for Salesforce data.
DuckDB as an In-Process Analytical Database Engine for Advanced Salesforce SQL Queries
DuckDB is an “in-process analytical database”. There are two things that set it apart from other databases:
- There is no database server – it is a program you download that handles SQL queries
- It can read and write file formats such as CSV, Parquet, and JSON, to and from the local file system and remote endpoints such as S3 buckets.
This allows a data analyst to write standard SQL queries that fetch, filter, join, and aggregate data across multiple data sources like CSV data on disk, Parquet data on S3, as well as queries to traditional database servers.
This approach is a game changer in the analytics space and enables you to run the most sophisticated distributed data lake query techniques on your laptop against whatever data sets you can download or fetch.
So the remaining challenge is to get your data into standard formats that DuckDB understands like CSV or Parquet. GRAX makes it easy to get your Salesforce data in these formats for data reuse and analytics.
See GRAX in Action!
Check out our demo video to see how GRAX can help you unleash your data’s potential.
DuckDB vs Native Salesforce Reporting for CRM Analytics
Salesforce’s native reporting isn’t terrible. It is built for a specific job, though. Report Builder and joined reports are great for short, simple-query reporting for sales managers that can build these with incredible speed and efficiency. However, the moment you request anything other than “show me this quarter’s pipeline by stage,” native reporting would immediately hit its ceiling.
Standard reporting only follows objects with a pre-defined relationship. Even joined reports are limited to a few blocks at a time, with limited cross-filtering between them. Limitations on rows and grouping also mean that large datasets get trimmed down or summarized before you even have a chance to explore them further.
Behind it all, there’s no real SQL to begin with: no CTEs, subqueries, or window functions. Something like formula fields or bucketing can draw an approximation of minor transformations but they’re nowhere near as complex as actual query logic should be.
So what’s Salesforce’s solution in this context? It’s called Tableau CRM (formerly Einstein Analytics), which is quite a powerful platform, but that platform has its own dataflows and licensing costs on top of what users already pay for Salesforce itself. Besides all that, it’s still a Salesforce-native software at its core, making it challenging to blend in a product usage log or a CSV of ad spend, among other data types.
This is where the combination of GRAX and DuckDB changes the equation:
| Native Reporting | Tableau CRM | DuckDB + GRAX | |
| Joins, CTEs, subqueries | No | Limited | Full SQL |
| Historical and point-in-time data | No (current state only) | Add-on required | Native, via GRAX history |
| Blend with external data | No | Difficult | Yes, any file or source |
| Row/complexity limits | Yes | Fewer, but present | None |
| Cost/skill required | Free, no-code | Paid, moderate learning curve | Free, requires SQL |
The trade-off is fair and honest: DuckDB doesn’t have a user-friendly drag-and-drop dashboard for a non-technical user. Yet, for anyone who actually needs to interact with Salesforce data in some way (join, combine), the combination of DuckDB and GRAX offers what native reporting and Tableau CRM don’t have.
AWS and DuckLabs: What the Acquisition Means for DuckDB Users
Amazon has signed a definitive agreement to acquire DuckLabs, the Amsterdam-based company behind DuckDB, the open-source analytical database that’s quietly become a favorite way to query data without standing up a warehouse. The deal is expected to close soon, with DuckLabs becoming part of AWS in early September.
Here’s the part that matters most for anyone building on DuckDB: Amazon isn’t acquiring the open-source project. DuckDB, along with related projects like DuckLake and Quack, stays free and open source under the MIT license, governed by the independent DuckDB Foundation. Hannes Mühleisen and Mark Raasveldt, DuckDB’s creators and DuckLabs’ co-founders, stay in Amsterdam, continuing to lead the technical direction of the project itself.
So what changed? The commercial team behind DuckDB now has AWS’s resources and distribution behind it. What didn’t change: the license, the governance, or the reason people reached for DuckDB in the first place.
Why this is worth a moment, even though DuckDB is still a small piece of the analytics stack
DuckDB isn’t Snowflake. It isn’t Databricks. It isn’t a Salesforce Data Cloud. In the grand scheme of enterprise analytics spend, it’s a small player. But that’s exactly what makes this acquisition worth noting. A lightweight, in-process SQL engine that runs directly against data you hold, in a format you control, just got validated hard enough that AWS wanted the team behind it.
The model DuckDB proved out was the ability to query your own data, in place, with real SQL, without a vendor’s warehouse in the middle. That approach is what made it worth acquiring.
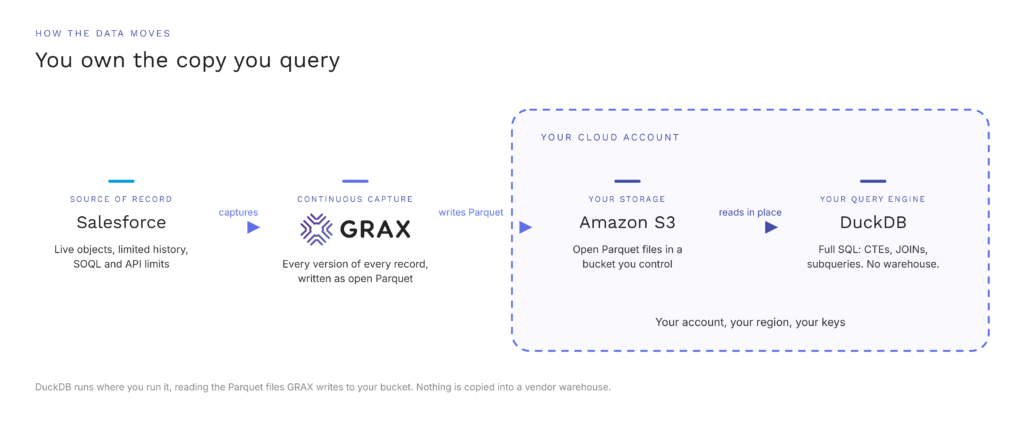
It’s the same bet GRAX made with the Data Lake.
What GRAX + DuckDB already gives you
We wrote about this in detail already: Run real SQL queries on Salesforce data with DuckDB + GRAX. The short version hasn’t changed:
- Full CTEs, JOINs, and subqueries against your Salesforce objects without SOQL’s limitations
- Years of history become queryable, without hitting Salesforce API limits
- No warehouse to license, size, or manage since DuckDB runs against the Parquet files GRAX already writes to your own S3, Azure, or GCP storage
Your data never leaves your cloud. You’re not waiting on a connector, a data stream, or a vendor’s ingestion schedule. You install DuckDB, point it at your bucket, and query.
The bigger message
Vendors get acquired. Roadmaps shift. Licensing changes. Support teams get folded into bigger orgs with different priorities. It’s the news cycle for anyone paying attention to the data tooling space this year.
The customers who aren’t scrambling when that happens are the ones who never handed their data to the tool in the first place. We believe you should own the data, own the format, own the cloud it sits in. The tools you query it with become swappable so you can choose the right tool for the job. That’s true whether the tool is DuckDB, Data Cloud, or whatever comes in the future.
Take ownership of your data and your AI/analytics stack. That’s the whole thesis. DuckDB just became AWS’s newest proof point for it.
Curious what querying your own Salesforce history with DuckDB actually looks like? Read the technical breakdown.
How to Connect Salesforce Data to DuckDB Step by Step
Connecting GRAX with DuckDB comes down to just a few steps once GRAX itself is set up and collecting your Salesforce information already. The steps are:
- Double-check that GRAX has access and configured API credentials.
- Select your strategy: querying GRAX live from DuckDB or exporting into files and loading them.
- Export the needed Salesforce objects from GRAX in whichever format you prefer (Parquet or CSV).
- Load exported data into DuckDB and begin querying the tables.
- Enable and configure incremental exports so that your DuckDB tables won’t become stale.
Export and Load Salesforce Data in Parquet and Other File Formats
Both the GRAX Search UI and Search API allow exports of any objects, field sets, or historical windows in CSV or Parquet format. The latter is the preferable option for most cases that are more complex than a quick and simple look: it’s compressed, columnar, and can be read by DuckDB natively without a dedicated importing step:
CREATE TABLE accounts AS
SELECT * FROM read_parquet(‘accounts_2024.parquet’);
That’s not to say that CSV cannot be used for the same task (read_csv_auto()), but Parquet has the advantage of loading noticeably faster than CSV when it comes to bigger exports, and it even keeps types intact.
Automate Incremental Salesforce Data Updates in DuckDB
Re-exporting everything for every new run is a massive waste of time that grows exponentially with your total data volume. What you can do instead is take advantage of GRAX’s time-window filtering for exporting just the records that were modified since the last sync time before appending or upserting them into your existing table:
INSERT INTO accounts
SELECT * FROM read_parquet(‘accounts_delta.parquet’)
WHERE Id NOT IN (SELECT Id FROM accounts);
Running this command on a schedule using Airflow or a simple cron script should keep DuckDB data up-to-date without any need for re-pulling the entire Salesforce history each time.
Salesforce and DuckDB Use Cases
SOQL limits aside, real SQL access to Salesforce data unlocks many potential advantages to the users of GRAX and DuckDB in Salesforce. Below, we offer three different scenarios that all utilize Salesforce data via DuckDB:
- Historical trend analysis.
- Relational rollups.
- Blending in data Salesforce never had to begin with.
Analyze Historical Customer Relationship Management Data Structures and Trends
Let’s say a sales ops lead was trying to determine the average number of open opportunities each rep was carrying at the start of the year and at the end of it as a snapshot instead of a trend. In native Salesforce reporting you simply can’t do this without a separate add-on focused on historical trending, and even then it’ll only cover a handful or so fields. Since GRAX stores all versions of every record, it’s easy to take two point-in-time snapshots and diff them directly into DuckDB:
WITH jan AS (
SELECT OwnerId, COUNT(*) AS open_jan
FROM read_parquet(‘opportunities_2023-01-31.parquet’)
WHERE StageName NOT IN (‘Closed Won’, ‘Closed Lost’)
GROUP BY OwnerId
),
dec AS (
SELECT OwnerId, COUNT(*) AS open_dec
FROM read_parquet(‘opportunities_2023-12-31.parquet’)
WHERE StageName NOT IN (‘Closed Won’, ‘Closed Lost’)
GROUP BY OwnerId
)
SELECT j.OwnerId, open_jan, open_dec, open_dec – open_jan AS change
FROM jan j JOIN dec d ON j.OwnerId = d.OwnerId
ORDER BY change DESC;
There’s no add-on, no data warehouse – only two export tasks and one join task.
Analyze Salesforce Opportunity and Account Data with CTEs, Subqueries, and Real SQL Queries
The roll-up-and-compare pattern like this is exactly the one that’s difficult in SOQL: you’ll need a formula field, a report on top of that formula field, a bucket field just in case to flag “above average” accounts, and even then there’s no guarantee that data would survive a re-run of the same numbers with a different average.
In SQL, all this can be done with a single query. The CTE rolls up open pipeline per account, then the outer query compares each account with the whole set’s average without intermediate fields or separate reports:
WITH OppTotals AS (
SELECT AccountId, SUM(Amount) AS TotalPipeline
FROM Opportunity
WHERE IsClosed = false
GROUP BY AccountId
)
SELECT a.Name, a.Industry, o.TotalPipeline
FROM OppTotals o
JOIN Account a ON a.Id = o.AccountId
WHERE o.TotalPipeline > (SELECT AVG(TotalPipeline) FROM OppTotals)
ORDER BY o.TotalPipeline DESC;
You will only have to switch the WHERE clause to use this same shape to answer many different questions, like accounts below average or accounts grouped by industry instead of a flat list.
Combine Salesforce Data with External Data Sources
Since DuckDB doesn’t really care about where a table would come from, joining Salesforce data with an external file is nothing more but a simple join. Here, we can match accounts to a CSV of website traffic data to learn what accounts are engaged the most online:
SELECT a.Name, a.Industry, w.monthly_visits
FROM Account a
JOIN read_csv_auto(‘website_traffic.csv’) w ON a.Website = w.domain
ORDER BY w.monthly_visits DESC
LIMIT 10;
It follows the same pattern for anything external you can bring into a file: product usage logs, support ticket exports, spend per account, marketing engagement metrics. Anything that has a column that DuckDB can join on, and Salesforce data can reside next to, can’t be done by a native Salesforce tool without middleware or even a separate integration platform.
GRAX Salesforce Data APIs
GRAX acts as a multi-purpose Salesforce data warehouse.
Its primary function is a Salesforce data collector, which when turned on starts capturing and organizing every version of every object into its GRAX internal data warehouse storage system. This powers its classic backup, archive, and restore capabilities.
But with all this Salesforce historical data captured and organized, GRAX also works as a data warehouse with a Search API which lets you quickly find and download Salesforce data by object, field sets, and windows of time across your entire Salesforce history.
The simplest way to get started is to use the GRAX Search UI to find and download some data as CSV. Common search jobs:
- All accounts (no filters)
- All accounts in North America (field filter)
- All accounts as they existed at the end of 2023 (historical time window)
To learn more check out our doc: https://documentation.grax.com/reuse-data/global-search.
A more powerful way is to use the GRAX Search API to script queries in Python. Some scenarios that are possible with a bit of scripting:
- All accounts as they existed at the end of every month in 2023 to analyze month-over-month data (12 search API calls)
- All Accounts, Cases, and Assets to join together for analysis (3 search API calls)
To learn more, take a look at our API Docs and GRAX Labs GitHub Repo.
Once we understand how to use GRAX to get Salesforce data out for reuse, we’re ready to do advanced analytics with DuckDB.
How GRAX Connects Salesforce and DuckDB
Now we’re ready to start writing SQL queries and have DuckDB go find the data in GRAX and do the analytics. This is accomplished with a few lines of Python script that connects the DuckDB SQL engine with the GRAX Search API to fetch data for analysis. You can see this at graxlabs/duckdb on GitHub.
We can start with something simple – counting all contacts. Salesforce data admins know that counting is something Salesforce and SOQL have trouble with for large data sets.
SELECT COUNT(*) FROM Contact;

---
Downloading Contact...

   count_star()
0        206084
Now we’re ready for some real SQL that shows us Contacts in an Account hierarchy.
WITH Contacts AS (
    SELECT
    AccountId, Email, CONCAT_WS(' ', FirstName, LastName) AS Name
    FROM Contact
),
Accounts AS (
    SELECT
    a.Id, a.Name AS Account,
    (SELECT Name FROM Account.csv WHERE Id = a.ParentId) AS ParentAccount
    FROM Account a
)
SELECT
c.*, a.Account, a.ParentAccount
FROM Accounts a
JOIN Contacts c ON c.AccountId = a.Id
WHERE ParentAccountName IS NOT NULL
LIMIT 20;

---
Downloading Contact...
Downloading Account...

Email:         contact@example.com
Name:          First Last
Account:       Subsidiary Corp
ParentAccount: Parent Corp

...
SQL experts can rejoice that we use Common Table Expressions (CTEs), JOINs, and subqueries. Anything analytics you can imagine doing in SQL is now possible.
To learn more, check out the following resources:
Salesforce DuckDB Performance and Data Governance Considerations
Real SQL access comes with real responsibilities, most of which revolve around keeping queries fast as data grows and keeping exported Salesforce data as secure as if it was within Salesforce from the get-go.
Optimize Queries for Large Data Sets with Select, Filter, and Join Operations
Even though DuckDB is quick, its constraints in terms of CPU and RAM are very much real. The way a query is shaped matters more here than against a server-backed database.
Try to filter and select only the relevant fields instead of full objects that get trimmed down later on; a file that was originally smaller means there’s less to scan on every query. Parquet should be favored over CSV for anything that’ll be queried repeatedly. Its columnar format allows DuckDB to skip non-selected columns instead of reading all the lines from start to finish. All CTEs and subqueries that get reused across several queries should materialize into a real table once without recomputing it each time:
CREATE TABLE open_opps AS
SELECT * FROM Opportunity WHERE IsClosed = false;
Excessively large historical exports should be queried by time window to keep everything responsive without the need to pull all of history at once.
Secure Salesforce API Access, Data Storage, and Privacy
There’s a lot of PII that exists in exported Salesforce data, and all that data stored into a Parquet file somewhere outside of Salesforce means Salesforce’s field- and row-level permissions aren’t attached to it anymore (DuckDB doesn’t enforce any of it either). It’s imperative for access control to happen upstream, be it via GRAX’s own permissions or via normal file storage security of the end storage location for that Parquet file.
The same approach should work for credentials, with GRAX API keys following least-privilege access and living as environmental variables:
Import os
api_key = os.environ[“GRAX_API_KEY”]
Conclusion
Thanks to DuckDB and GRAX, we’re now able to analyze our Salesforce data with SQL.
All the limits of SOQL are gone. We can join, transform, filter, window, and aggregate large amounts of Salesforce data without leaving our SQL editor.
All the hassles of databases are gone. We didn’t need to set up an expensive database, data warehouse or ETL jobs before we could start doing analytics.
The result is getting insights from our business data in minutes.
FAQ
Can I use CTEs and subqueries to join Salesforce objects and historical record versions in DuckDB?
Yes, DuckDB handles standard SQL with CTEs, subqueries, window functions, and joins across all exported Salesforce objects, including multiple historical versions of the same object, allowing comparisons of records in different states over time.
Can GRAX export only specific Salesforce objects, fields, or time periods for DuckDB analysis?
GRAX’s Search UI and Search API lets users filter data by object, by field-set, and by time range so that you can pull exactly what you need. It can be the latest value of a single object or even something as simple as a historical view.
Can DuckDB analyze GRAX-exported Salesforce data in external CSV, JSON, and Parquet file formats?
CSV, JSON, and Parquet are supported by DuckDB natively, without any import or conversion step necessary; it can query these files directly from remote storage like S3 and not simply a local disk. Parquet tends to be better for larger exports as they are compressed and columnar, whereas all three formats can work directly in SQL queries.